The Platform
Precomputing 0.1.1 is one policy language and one SQLite file format, with two runtimes that keep the file current and three products built on them. The SQL runtime compiles a policy into plain SQLite triggers. The Engine runs the same policy in a Go binary with SQLite built in. The Meter counts usage for billing, exactly. Logs keeps a log dashboard’s answers ready while the raw lines stay on site. Traces keeps the model calls of AI agents, each piece once, and meters them. An MCP server lets AI agents read any file’s answers.
Eight live demos run the real code in your browser. Seven run on simulated or generated data: API traffic, a trading day, a month of AI usage, a web shop’s logs in two demos, an AI agent that reads the first four demos’ files over MCP, and a day of coding-agent calls. The eighth takes every change to every Wikipedia from Wikimedia’s public stream as it happens. In all eight the code and every check are real. The code is open source under the Apache License 2.0, at github.com/precomputing/precomputing.
Where it stands. Version 0.1.1: the 0.1 platform, complete for what it covers and checked hard on simulated data, with an MCP server, tokens for the HTTP server and Traces added. Next it needs real traffic from teams who try it.
- 7.9 times smaller: three hours of API traffic kept as ready answers, with every p99 within 0.65% of the exact value.
- 100 kills: the Engine stopped without warning while it takes in a trading day, with no acknowledged trade lost.
- $5,804.56: a month of AI usage invoiced, equal to a separate recount to the billionth of a dollar.
- 120 times fewer bytes: a log dashboard sent upstream, with every count and sum still equal to the raw lines and every p95 within 1%.
- 2,081 times fewer tokens: an AI agent’s four questions answered over MCP from those files, against the raw data behind the answers, with all 19 checks passed.
- 14 times smaller: a day of AI agent calls with each piece kept once, all 2,045 calls rebuilt from the file byte for byte and every cost equal to a recount.
On this page: In brief · The language · The file · SQL · Engine · Meter · Logs · Live data · MCP · Traces · Tests · Features and limits · Where it stands
The Platform in Brief
| Part | Status | Key figures |
|---|---|---|
| Language | Complete for 0.1 | Streams, rollups, quantile sketches, samples, kept anomalies and precomputes; exact streams, quotas and streams from logs |
| SQL runtime | Complete | A policy compiles to tables, views and one trigger per stream. Runs in SQLite 3.35 or newer with the math functions, including in the browser |
| Engine | Complete | One Go binary of about 13 MB with SQLite 3.53.4 built in; 5.9 MB for the browser with the MCP server and Traces, 1.6 MB compressed. 12 to 17 times faster than the triggers on Demo 2’s trades |
| Meter | Complete for 0.1 | Retries counted once, late reports placed in their hour, months that close, quotas read in 10 to 13 µs |
| Logs | Complete for 0.1, with no forwarder yet | Templates learned with Drain, a dashboard imported as a policy, every line kept on site for 48 hours, past incidents recognized from saved fingerprints |
| MCP | New in 0.1.1 | Five tools that only read, over the 2026-07-28 revision and the older handshake; in precomputing serve with tokens, over stdio and in the browser |
| Traces | New in 0.1.1, in simulation | Each message and tool list kept once by SHA-256, any call rebuilt byte for byte, secrets masked, cost by run, repository and source with budgets |
| Tests | Extensive, on simulated data | Engine and triggers compared value for value; 100 kills in the crash lab; Drain’s published accuracy on all 16 Loghub datasets |
| Demos | Eight: seven on simulated or generated data, one on Wikipedia’s live changes | 1,080,198 requests, 4,048,210 trades, 373,351 usage reports, two runs of log lines (281,164, then 2,375,957), four questions over MCP and 2,045 agent calls, each checked against a recount; Wikipedia’s changes checked every 30 seconds as they arrive |
| Code | Open source, Apache License 2.0 | About 13,900 lines of Go and 3,100 lines of Go tests, at github.com/precomputing/precomputing. The first public release, 0.1.1-alpha, has ready-made binaries for Linux |
| Readiness | Alpha | Validated on simulated data. Not yet run on anyone’s production traffic |
One Language
A policy is a short text file that says which streams of events exist, which answers to keep ready and how long each level of detail lives. The compiler checks it and refuses a mistake with its line and a plain message.
stream latency {
  key   endpoint text
  value ms real

  raw     keep 5m
  rollup  10s keep 24h
  rollup  1m  keep 30d  quantiles ms
  rollup  1h  keep 1y   quantiles ms

  samples 3 per 1m
  anomalies ms log z > 4 keep 20 per 1m
}

precompute p99_ms = p99(latency.ms) by endpoint
That is Demo 1’s policy with one of its three precomputes. The whole policy compiles to 147 lines of SQL. The language has two ways of keeping detail. Streams let detail fade on a schedule, while unusual events stay whole. Exact streams keep every event until a business deadline has passed, such as an invoice that can no longer be disputed. The policy language explains every line.
One File
Every runtime writes the same SQLite layout: a raw table, a table of window summaries, the sketch buckets, samples, kept anomalies and one view per precompute. The file also holds its own policy and the statements that let old detail fade, so any SQLite tool can open it and understand it. The Engine’s file and the triggers’ file are the same, value for value, and either runtime can carry on in a file the other wrote. The file, table by table
The SQL Runtime
The compiled SQL runs inside any SQLite database. Events go in with INSERT, and the triggers keep every answer current on the same insert. Nothing else runs. Demo 1 measures it on three simulated hours of API traffic for a small web service, five endpoints at about 100 requests a second:
| What | Result |
|---|---|
| The three hours | 1,080,198 requests, with 300 planned slow requests and a two-minute outage |
| Storage | 4.5 MB for the precomputed file against 35.2 MB for a plain table of the same requests: 7.9 times smaller. Of the file, 1.2 MB is the last five minutes kept whole |
| Accuracy | Counts and averages exact. Every p99 within 0.65% of the exact value |
| Unusual requests | All 300 planned slow requests kept whole. During the outage, 1,111 of 1,395 requests flagged and 40 kept whole under the 20-a-minute cap |
| Reading | All 15 answers in 2 to 5 ms from the precompute views, against 2 to 3.5 seconds from the plain table |
From a headless run of the demo’s own code with the page’s SQLite WebAssembly build. The same answers were checked again in native SQLite.
The Engine
The Engine runs the policy in memory and writes what changed to the file at every checkpoint, in one transaction. Senders number their events. The file records the last number it holds from each sender in the same transaction, so after a crash a sender resends from there: nothing is lost and nothing counts twice. Measured on a shared two-core cloud server (Intel Xeon at 2.8 GHz). Speeds there change from one day to the next, in some runs by a third or more, so they are given as the range of our runs:
| Run | Result |
|---|---|
| Demo 2’s trading day on the command line, 4,048,210 trades, into a file on disk with a full sync every 10,000 trades | 12 to 16 seconds in our runs, 258,000 to 337,000 trades a second. Every closed candle and the quote board identical to a recount of every trade |
| The first 200,332 trades through the Engine and through the compiled triggers | 450,000 to 570,000 against 26,700 to 37,000 trades a second, 15 to 17 times faster. The two files: 122,793 rows, 576,218 values, identical |
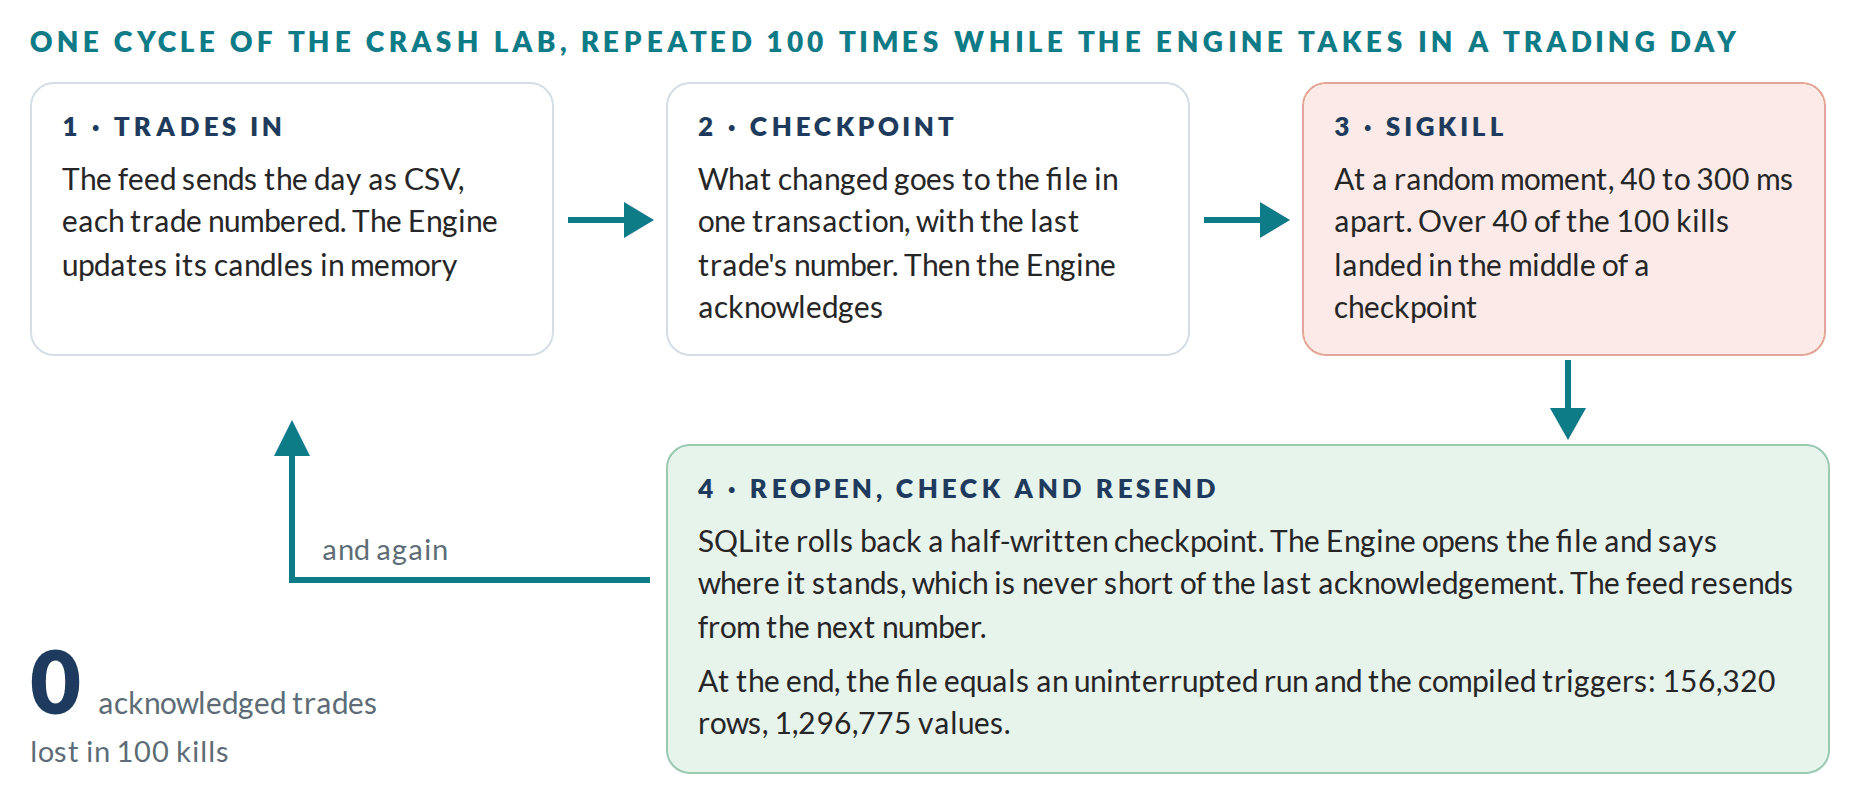
| The crash lab: the Engine killed without warning 100 times while it takes in the day | Over 40 kills in the middle of a checkpoint (42 and 45 in two runs). Acknowledged trades lost: 0. The final file identical to an uninterrupted run and to the triggers: 156,320 rows, 1,296,775 values |
| Demo 2 in Chromium on the same machine | 170,000 to 220,000 trades a second while writing the file five times a second. Back from a pulled plug in about 0.2 seconds |
The crash lab kills the Engine with SIGKILL 40 to 300 milliseconds apart, restarts it, checks that the file never holds less than the last acknowledgement, and resends from where the file stands.
The Meter
The Meter is an exact stream with precomputes by customer and month, and a quota. Retried requests are refused by their id, late reports count in the hour they happened, and a month closes a day after it ends. Prices sit in the same file, so an invoice is one SQL view over totals that are already added up. Demo 3 runs a month of invented AI usage: six customers on three plans, three models and two gateways.
| What | Result |
|---|---|
| The month | 366,118 requests served and 373,351 reports sent, retries included |
| Retries | 7,219 reports refused as repeats. No request id appears twice in the file |
| A six-hour outage | 625 held reports delivered when the link came back, each counted in its own hour |
| A queue stuck at the month’s end | 642 reports delivered after September closed, all refused as closed. The invoices did not change |
| September’s invoices | $5,804.56 due against $3,337.84 of model cost. Every line and amount equal to a separate recount, to the billionth of a dollar |
| Late reports | All 8,215 hourly windows equal to the recount, request for request and token for token |
| A quota check | One read of a view: 10 to 13 microseconds in WebAssembly |
| The file | 25.3 MB at the end of the month, 1.9 MB after the dispute window, with the invoices unchanged |
| Natively | The Engine takes the same reports in 2.3 to 3.3 seconds, 113,000 to 162,000 a second. Its tables equal the ones the browser’s SQL runtime wrote, value for value: 453,536 rows, 2,949,652 values. Only the price list and quota limits the demo adds are left out |
Logs
The log reducer sits next to the services that write the logs. It learns what kind of line each line is, keeps every line in a local file for 48 hours, and keeps ready the answers a dashboard shows. Upstream go those answers, the error lines, a few examples and any new kind of line. Demo 4 runs two hours of an invented web shop’s logs, about 39 lines a second on average.
| What | Result |
|---|---|
| The two hours | 281,164 lines, 25.5 MB, 19 templates |
| Sent upstream | 212 KB in 124 batches and 7,896 events: 120 times fewer bytes and 36 times fewer events than the lines |
| The dashboard, drawn from what was sent | 6,231 counts and sums identical to a recount of the raw lines, 840 p95 values within 1%, the top 10 searches identical |
| The payment incident | Caught as a new ERROR template 2 seconds after its first line |
| At Datadog’s list prices | About $173 a month with every line upstream, $4.84 with what was sent (list prices checked 29 September 2026) |
| Kept on site | All 281,164 lines in a 39.8 MB file. A search for one word over all of them takes 0.1 to 0.2 seconds |
| Natively | precomputing put --lines takes the same lines in 1.8 to 2.6 seconds, 108,000 to 156,000 a second |
Templates are learned with Drain, a published online log parser. The Go port follows the reference implementation step by step. On each of the 16 Loghub samples of 2,000 lines, with the published settings, its grouping accuracy equals Drain’s published figure:
| Dataset | Accuracy | Dataset | Accuracy |
|---|---|---|---|
| HDFS | 0.9975 | Linux | 0.6900 |
| Hadoop | 0.9475 | Android | 0.9110 |
| Spark | 0.9200 | HealthApp | 0.7800 |
| Zookeeper | 0.9665 | Apache | 1.0000 |
| BGL | 0.9625 | Proxifier | 0.5265 |
| HPC | 0.8870 | OpenSSH | 0.7875 |
| Thunderbird | 0.9550 | OpenStack | 0.7325 |
| Windows | 0.9970 | Mac | 0.7865 |
The average is 0.8654, the published figure. Sources: the Drain paper, Drain’s results on Loghub and Loghub.
Incident Déjà Vu
Demo 6 keeps a day of the same shop’s logs and asks every ten seconds which incident written down before looks like what stands out now. The comparison is plain SQL in the same file. A fingerprint is the set of templates far from their usual rate, and writing an incident down saves its fingerprint beside it, with an example line of each template.
| What | Result |
|---|---|
| The day before | 2,133,322 lines, 25 templates and six incidents written down, in a 3.7 MB file, 0.73 MB compressed. Built again from the same lines, it has the same bytes |
| Today’s two hours | 242,635 lines and five incidents. The three kinds from the day before named right 8 to 10 seconds after they began. The new kind flagged as new after 5 seconds and, once written down, its return named 10 seconds in |
| False alarms | None in 721 checks today, nor in 1,379 minutes of the day before |
| 20 more days at random | Known kinds named right 80 times out of 80, 12 seconds after they began at the median and 50 at most. New kinds flagged as new 20 times out of 20. None named wrong |
| A check | Two SQL views, read in 4 to 5 ms on average and 35 ms at most |
| Natively | precomputing put --lines wrote the same file from the same 2,375,957 lines: 328,955 values, 0 differences |
Live Data
Demo 5 connects the browser to Wikimedia’s public stream of recent changes, every change to every Wikimedia wiki as it is made, and hands each change to the Engine in the page. Three streams keep the answers ready: every change by wiki, kind, and bot or person, and for the last hour each article and each person on it. The recount runs in the page too, so the checks run on live data. Live numbers depend on the moment, so the ones published here come from 75 minutes of simulated changes through the same code:
| What | Result |
|---|---|
| The changes | 112,985 counted, with 1,096 repeats dropped and 96 of the stream’s test events skipped |
| Checks | 150 during the run and a full one at the end: 99,992 of 99,992 counts and sums equal the recount |
| The file | 9.6 MB after 75 minutes, most of it the last hour of articles, which then fades |
| Natively | precomputing put --format json wrote the same file from the same changes: 1,596,566 values, 0 differences |
| Privacy | No user name or edit summary is kept. People are counted by a number made from the user name and a random value for each visit |
MCP
An MCP server answers at /mcp in precomputing serve, beside the HTTP API, and over stdio as precomputing mcp FILE. Its five tools only read. describe_file says what a file keeps and for how long, get_answer reads a precompute for a key and a period, get_windows reads window summaries over a time range, get_kept reads events kept whole, and query runs one read-only SQL statement. Answers come back as short CSV text with a line of context, sized for a model to read. Demo 7 gives each of the first four demos’ files a server of its own, faded as its policy says, and asks four questions.
| What | Result |
|---|---|
| The four questions | 7 tool calls and 4 file descriptions, 2,561 tokens in all. The raw data behind the answers would take 21.3 MB as CSV, about 5.3 million tokens: 2,081 times more |
| Checks | All 19 figures in the answers equal to a count of the raw events by separate code, percentiles within 1% |
| Native against the browser | The same calls to precomputing mcp on the same files: 11 tool results and 4 tool lists, identical to the byte |
| Official clients | The MCP TypeScript client, version 2 on the 2026-07-28 revision and version 1 on the older handshake, over HTTP and stdio: every combination passes on all four files |
| Tokens | Without a token the server answers 401. A read token that posts events gets 403, and --read-only takes no events at all |
| A real agent | Claude, through the official client over HTTP with a read token, answers four questions of its own in 18 calls. The recording is on the demo page |
Tokens are estimated as a quarter of the bytes. The files are the ones the demos write, as their policies leave them once short-lived detail has faded.
Traces
An agent sends the whole conversation again with every model call, so a tracer that stores each call whole stores the start of every run many times over. Traces keeps each message and each tool list once, under the SHA-256 of its bytes, and each call as the list of its pieces with its size and SHA-256. A view rebuilds any call with SQL alone. Secrets are masked by pattern before anything is hashed or stored. Every call also goes to two exact streams, one event for the call and one for each source of its input, so a policy keeps cost by run, repository, model and source, and a budget per repository is a quota. Demo 8 runs a day of 100 coding-agent runs on 30 repositories, generated in the fields of a public dataset of real runs.
| What | Result |
|---|---|
| The day | 100 runs, 2,045 model calls, 4,190 messages |
| Bytes | 90.9 MB of requests as sent, kept in 6.5 MB of trace tables with their indexes: 14 times smaller. 4,092 pieces |
| Rebuilt | All 2,045 calls rebuilt from the file with SQL, each the request as sent, byte for byte |
| Secrets | 4 planted in 3 runs, 4 masked, none left in the file |
| Cost | $1.46 for the day at example prices, equal to a recount for every run, repository, source and model, to the billionth of a dollar. The two streams give the same total |
| A stuck run | 67 calls in 12 minutes for $0.46, about 46 times the median run. Its repository passed its $0.20 budget for the day at call 45 |
| Reported twice | A finished run sent again: every call refused as a repeat, costs unchanged |
| Natively | precomputing traces keeps the same day in 0.8 to 1.0 seconds. Its file equals the browser’s: 19 tables, 40,043 rows, 231,641 values. Only the demo’s budget limits are left out |
Token counts come from the o200k_base tokenizer, and the provider’s prompt cache is modeled: a call’s input is served from the cache up to the previous call’s input when that call was sent less than five minutes before. Prices are examples: $0.40 a million fresh input tokens, $0.04 cached, $1.60 output.
Tests
Every test runs on simulated data, except the Drain check, which uses the public Loghub samples. All pass.
| Suite | What it checks | Result |
|---|---|---|
| Parser and compiler | Every example policy compiles to the expected SQL; every mistake is refused with its line and a clear message | Pass |
| Engine against the triggers | The same events through the compiled triggers and through the Engine, with late events, zeros, price jumps and day boundaries among them; the two files compared value by value | Identical. Three small deliberate changes to the Engine’s rules each make the comparison fail, so it is a real check |
| Hand-over | A file filled by the triggers carried on by the Engine, and the other way round | Identical to a file made by one runtime alone |
| Crashes in the tests | The Engine stopped at random points of three workloads and resumed from its file | Identical to an uninterrupted run |
| The crash lab | A native process killed with SIGKILL 100 times while it takes in the trading day | 0 acknowledged trades lost; final file identical |
| Exact streams | Repeats, late reports and closed months, in the Engine and in the triggers | Identical, refusals included |
| Logs | The reducer against the compiled triggers; stopped without warning again and again; fast paths against the regular expressions they replace | Identical, templates included |
| Drain | The 16 Loghub datasets with the published settings | Accuracy equal to the published figure on every dataset |
| MCP | The tools, errors and headers of the protocol; the same calls answered by the native and the browser builds; both official clients on all four files | Identical; every combination passes |
| Traces | Every call of the generated day rebuilt from the file; masking with and without its quick tests on 20,000 made-up texts; a file opened again; the native file against the browser’s | Identical, to the byte |
| The eight demos | Each run checked by separate code that recounts from the events as they were sent and never reads the file; in the Wikipedia demo, every 30 seconds | 0 differences in every run, the Wikipedia demo’s on simulated changes |
| Demos 5 and 6, natively | The same changes and log lines through precomputing put, the files compared value by value |
Identical: 1,596,566 and 328,955 values |
Features and Limits
| Feature | What 0.1.1 supports | Limits |
|---|---|---|
| Streams | Keys, values and derived values; raw events kept for a set time; rollups of any length | Values are numbers and may not be null. Time in seconds, periods in UTC |
| Answers | count, sum, avg, min, max, first, last and any percentile, by keys, per hour, day or month | Percentiles within 1% by default, from quantile sketches |
| Unusual events | Kept whole against a running baseline per key, by level or by step | One anomaly rule per stream |
| Exact streams | Repeats refused by id, late limit, closing periods, raw events kept through a dispute window, and since 0.3 a guard against clocks that run ahead | No percentiles. With ahead, the machine that counts needs a correct clock |
| Quotas | A limit beside any per-period sum or count, read as one view | Events over the limit are still counted, because they happened |
| Logs | One line format per policy, key=value fields, templates per service and level, dashboard import, and since 0.3 OpenTelemetry log records over OTLP/HTTP | JSON lines are read as text. Import reads count, rate, sum, avg, min, max, percentiles and top lists |
| Metrics | Since 0.3, OpenTelemetry gauges, sums and histograms over OTLP/HTTP, cumulative ones turned into deltas per series | Histograms keep their count, sum, minimum and maximum, not their buckets. Summaries and exponential histograms are refused |
| Runtimes | Compiled triggers in any SQLite 3.35 or newer with the math functions; the Engine on the command line, over HTTP or HTTPS and in the browser | One writer per file |
| MCP | Five tools that only read; tokens over HTTP; stdio for local agents | SQL one statement at a time, stopped after five seconds |
| Traces | Whole runs from the command line or the browser; secrets masked by pattern; cost by run, repository, model and source; budgets as quotas | No hook into agent frameworks yet. A secret of a shape it has no pattern for is stored as it came |
| Changes | Since 0.3, precomputing migrate adds streams, rollups, precomputes and quotas to a running file and changes how long detail is kept |
What is new starts empty at the migration. A change to what is already counted is refused |
Where It Stands
Maturity by Part
| Part | Maturity | Evidence | Gap to close |
|---|---|---|---|
| Language and compiler | Working, tested | Golden tests for every example; errors refused with clear messages | Feedback from policies other people write |
| SQL runtime | Working, tested | Demo 1; native SQLite check; same file as the Engine | Measured inside more hosts, such as phones and Cloudflare Durable Objects |
| Engine | Working, tested | Equivalence tests, the crash lab, Demo 2, Demo 5 on simulated changes | Demo 5 on the live stream, real feeds from teams, long runs, memory with many keys |
| Meter | Working in simulation | Demo 3 checked to the billionth of a dollar; native and browser files equal, value for value | A pilot with real usage and real invoices |
| Logs | Working in simulation | Demos 4 and 6; Loghub accuracy as published; OTLP records checked against requests from the official OpenTelemetry classes | A forwarder, JSON lines |
| MCP | Working, tested | Demo 7; both official clients; native and browser answers identical | Real agents on real files |
| Traces | Working in simulation | Demo 8; every call rebuilt; costs equal to a recount; native and browser files equal | Real runs, and a hook in the agent’s path |
| Security | Started in 0.1.1 | Read and write tokens, a read-only mode, HTTPS since 0.3, secrets masked in Traces | A review by someone outside the project |
| Use in the field | None | None | Pilots |
Against the Alternatives
| Part | What already exists | What Precomputing adds |
|---|---|---|
| SQL runtime | SQLite triggers written by hand as materialized views; Turso’s live materialized views, experimental, with no windows or retention | Rollups, sketches, kept anomalies and retention from a few declared lines, in any SQLite, with nothing new to install |
| Engine | PocketBase, Go and SQLite in one file as an application backend; RRDtool-style rollups in their own formats | The same policy as the SQL runtime at native speed, in an ordinary SQLite file, with sequence numbers for crashes |
| Meter | Billing platforms such as OpenMeter, Lago, Metronome and Orb; LiteLLM budgets on counters and a database | Exact counting in the same language and file as everything else, inside your own SQLite. It counts usage, and billing stays with a billing system |
| Logs | Pipelines such as Cribl, Grepr, Sawmills and Observo; Grafana Adaptive Logs; OpenTelemetry’s log deduplication processor and signal-to-metrics connector | Reads a dashboard to decide what to keep ready, and keeps every line on site in a file you can search |
| MCP | MCP servers for SQLite and other databases, such as mcp-server-sqlite, that let an agent read the schema and run its own SQL | Ready answers sized for a model, and a description of what the file keeps and for how long, so the agent asks for answers before it writes SQL |
| Traces | LLM observability tools such as Langfuse and LangSmith, which record each call with its input, output, tokens and cost; OpenTelemetry’s GenAI conventions for recording model calls | Each piece kept once however many calls resend it, any call rebuilt byte for byte, and costs exact in the same file as the meter, with budgets as quotas |
The fair reading: each field already has tools that are larger and more proven. Precomputing’s case rests on one language and one file across all these jobs, and so far it has been shown on simulated and generated data only.
Technical Risks
- One writer per file. Senders report to one Engine process or into one SQLite database that runs the triggers. Reads can run alongside.
- Clocks in exact streams. An exact stream’s clock is the newest event time it has counted. Without
ahead, one report stamped far in the future moves that clock for every sender and could close a month early. Withahead, such a report is refused, and the machine that counts needs a correct clock instead. - Many keys. The Engine keeps one baseline per key in memory and reads the newest window of every key when it opens. A key such as a user id, with millions of values, makes both memory and the file grow. In the Wikipedia demo every article edited becomes a key, which is why its article streams keep only an hour. Closed windows leave memory at each checkpoint, but each key’s name and baseline stay as long as the Engine runs, so a page left connected for hours keeps growing slowly.
- The last bit of a logarithm. Sketches and log anomalies use the logarithm, whose last bit can differ between platforms. For Demo 3 the native Engine and the browser’s SQL runtime wrote the same values in every table; for Demo 4 one value out of 1,794,042 differs by two units in the last place.
- Logs depend on the format. A line that does not match the policy’s format is counted and skipped. Templates depend on masking identifiers well, and JSON lines are read as plain text.
- OTLP retries. OpenTelemetry exports carry no sequence numbers. The server knows a retried request by its exact bytes for an hour; a sender that rebuilds a request differently after a crash counts it twice.
- Secrets by pattern. Traces masks the secrets it has patterns for: cloud keys, GitHub, Slack and API tokens in the shapes providers give them, private keys and bearer tokens. A secret of another shape is stored as it came.
Every figure on this page was measured on the 0.1 code, or on 0.1.1 for MCP and Traces, in September 2026 unless it is marked otherwise; the 0.3 additions are described, not measured. The prototype includes the commands that reproduce the native and headless figures, and the demo pages show the browser figures as they run.